Benchmarking Web Scraping APIs Under Real Anti-Bot Pressure
Most scraping benchmarks measure only whether pages return, not whether they're usable by AI models.
Priya Nandakumar
Most scraping benchmarks measure only whether pages return, not whether they're usable by AI models.
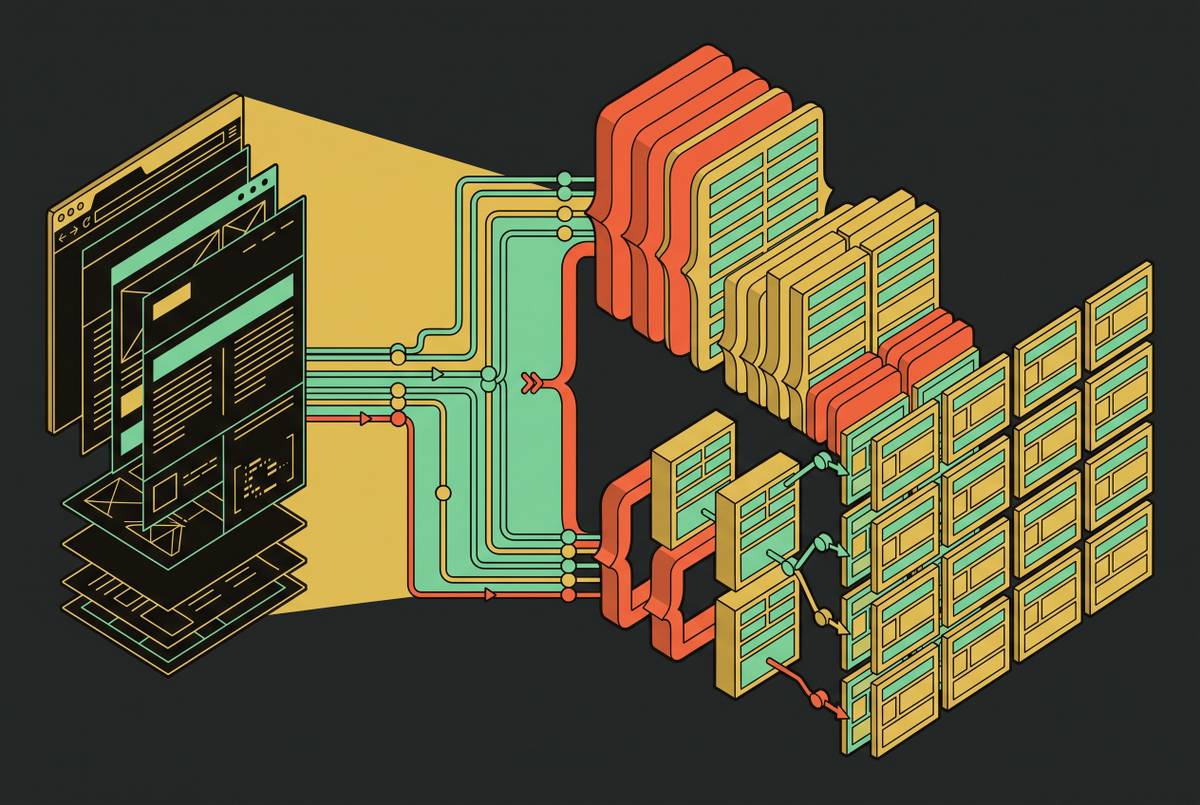
Clean HTML conversion to Markdown is the foundation for effective AI pipelines.
Schema quality determines extraction accuracy, not JSON validity.
Detect throttling from response signals before hard blocks arrive.
Avoid CAPTCHAs first, then solve what you can't prevent.
Distributes scraping traffic across rotating IPs to avoid detection and bans.
Solving CAPTCHAS at the wrong architectural layer wastes money and latency.
Fix three production crashes: zombie processes, shared-memory exhaustion, and unclosed contexts.
Secrets sprawl across AI pipelines puts projects at risk without proper centralized management.
Webhooks cut request waste by 98% compared to polling for async scraping jobs.
Agents need sub-second data access at every hop or their decisions become obsolete.
Web data APIs fail silently in ways generic error handling can't catch.