Headless Browser Memory and Crash Management in Long-Running Scrapers
Fix three production crashes: zombie processes, shared-memory exhaustion, and unclosed contexts.
Headless browser scrapers fail differently than ordinary HTTP scrapers because a browser is a multi-process application with its own memory and crash behavior, not a single function call. Teams running these systems in production hit three distinct failure modes: zombie process accumulation, shared-memory crashes under Docker, and memory leaks from browser contexts that never get closed. Each has a specific, fixable cause and a specific mitigation. The best web scraping APIs for extracting data at scale, including Context, exist in large part because handling all three correctly, every time, across thousands of concurrent jobs, is genuinely hard infrastructure work.
Three distinct failure modes cause headless browser scrapers to crash or degrade in long-running production environments. The first is zombie process accumulation: child processes that finished but were never reaped pile up silently in the process table across jobs, and the mitigation is explicit process cleanup paired with a scheduled container restart cycle. The second is the /dev/shm crash, where Chrome exhausts Docker's default 64-megabyte shared-memory allocation and the renderer dies without a clear error; passing --disable-dev-shm-usage at launch redirects Chrome to write to /tmp instead, preventing the crash entirely. The third is memory leaks from unclosed browser contexts, where an exception thrown mid-job skips cleanup and leaves the context open indefinitely; the fix is wrapping all browser automation in try/finally blocks so that browser.close() and context cleanup run on every code path, whether the job succeeds or fails.
Why do headless browsers fail differently in long-running production environments?
A browser launch is several processes at once: a browser process that runs the show, a GPU process, and a separate renderer process for every isolated site context the browser opens. Each of these carries its own base memory footprint before a single page has loaded.
Modern single-page applications make the math worse. A page's cost depends on how much it allocates for its DOM tree, its JavaScript heap, and its image buffers, and that number moves depending on what the page actually does. A news article and a dashboard full of live charts do not cost the same amount of memory, even if both load in the same browser tab.
Chrome assumes by default that you have a desktop machine with memory and CPU to spare. That assumption is accurate for someone's laptop and wrong for a container with a modest memory allocation or a budget VPS running a dozen scraping jobs at once. Running Chrome's defaults on constrained server hardware isn't a minor mismatch, it actively works against the environment it's running in.
Three common mistakes make the underlying architecture problem worse: spinning up a brand-new browser instance for every single request, failing to close contexts and pages when something goes wrong mid-job, and letting temporary files and orphaned processes pile up unnoticed. None of these failures are random. Each one is a predictable consequence of how a browser's process model collides with limited server resources, and each has a corresponding fix. The rest of this piece works through them in order.
Zombie process accumulation in containers
The first failure mode is quiet. Zombie processes are child processes that already finished, but their parent never cleaned them up (reaped them). A zombie doesn't use CPU. It doesn't hold meaningful memory. It sits in the process table as a single leftover entry, produces no output, and throws no error.
That quietness is what makes it dangerous in a container. On a developer's laptop, a reboot clears all of this out automatically. A long-running container doesn't get that reset. It keeps running, job after job, so every zombie process from every scraping job that didn't clean up properly just stays where it was left.
The failure doesn't look like a crash. That gradual signature is easy to mistake for an ordinary memory leak in the application code, but it isn't one. So you need to watch the process count directly, not just application memory, because if the process count rises across scraping jobs, that points straight at zombie accumulation. Beyond monitoring, you need explicit process cleanup paired with a container restart schedule to actually fix it. Code alone will not solve what is, at its core, a container lifecycle problem.
The /dev/shm crash: why Chrome's shared-memory dependency causes the most common Docker failure
Chrome depends heavily on shared memory, and Docker's default allocation for /dev/shm is small, often just 64 megabytes. When Chrome fills that space, the renderer crashes. The browser process itself usually survives. The parent script may never see an error at all, since it just hangs, or it silently returns bad data, with nothing in the logs pointing at the real cause.
This is the single most common Docker failure for headless browser scraping, and it is purely a configuration issue, which makes it preventable. If you pass --disable-dev-shm-usage at launch, Chrome writes to /tmp instead, so it skips the limited shared-memory partition. That one flag belongs on the short list of launch settings that should be treated as mandatory in any containerized deployment.
Chrome's defaults were never built for servers, so you should check the full set of launch flags as a starting point, not an afterthought. A few more belong in the same audit. --disable-gpu removes a process that adds instability without buying anything, since there's no screen to render to in a headless server context. --no-sandbox sometimes becomes necessary in unprivileged containers, but it turns off real security protections, and the better fix is configuring container capabilities correctly rather than reaching for that flag as a default.
This failure and zombie accumulation differ in practice, and that difference matters for how each gets caught. The shared-memory crash is sudden: a renderer dies mid-job, possibly hanging the worker. Zombie accumulation is gradual, building over hours. They need separate detection strategies, and conflating the two leads to chasing the wrong fix.
Memory leaks from unclosed browser contexts
The third failure mode lives in the code itself, not in deployment configuration. Browser contexts are isolated sessions inside the same browser process. They don't share cookies or cache with each other, but they do share the underlying process. A context that never gets closed holds onto its memory allocation for as long as the browser runs.
When a page loads and the job finishes cleanly, it almost always closes its context properly. The danger sits in the error path. If an exception gets thrown during navigation or data extraction, it skips past the cleanup step entirely, and the context stays open, invisible, until the browser has run long enough for the leak to show up in memory graphs.
The fix is structural rather than clever: wrap browser automation in try/finally blocks so that browser.close() and context cleanup run no matter what happens inside the page operation, success or failure. The correct default for managing any resource with an explicit open-and-close lifecycle is to run cleanup no matter what happens, the same discipline used for file handles or database connections, not an extra safety measure bolted onto the real code.
If you inspect the process table, you'll see this failure mode looks different from zombie accumulation. Context leaks raise the memory footprint of processes that are still alive, so they add no new entries to the process table. That distinction is what tells an engineer which of the two problems they're actually looking at.
Browser pooling as the architectural answer to startup cost and memory predictability
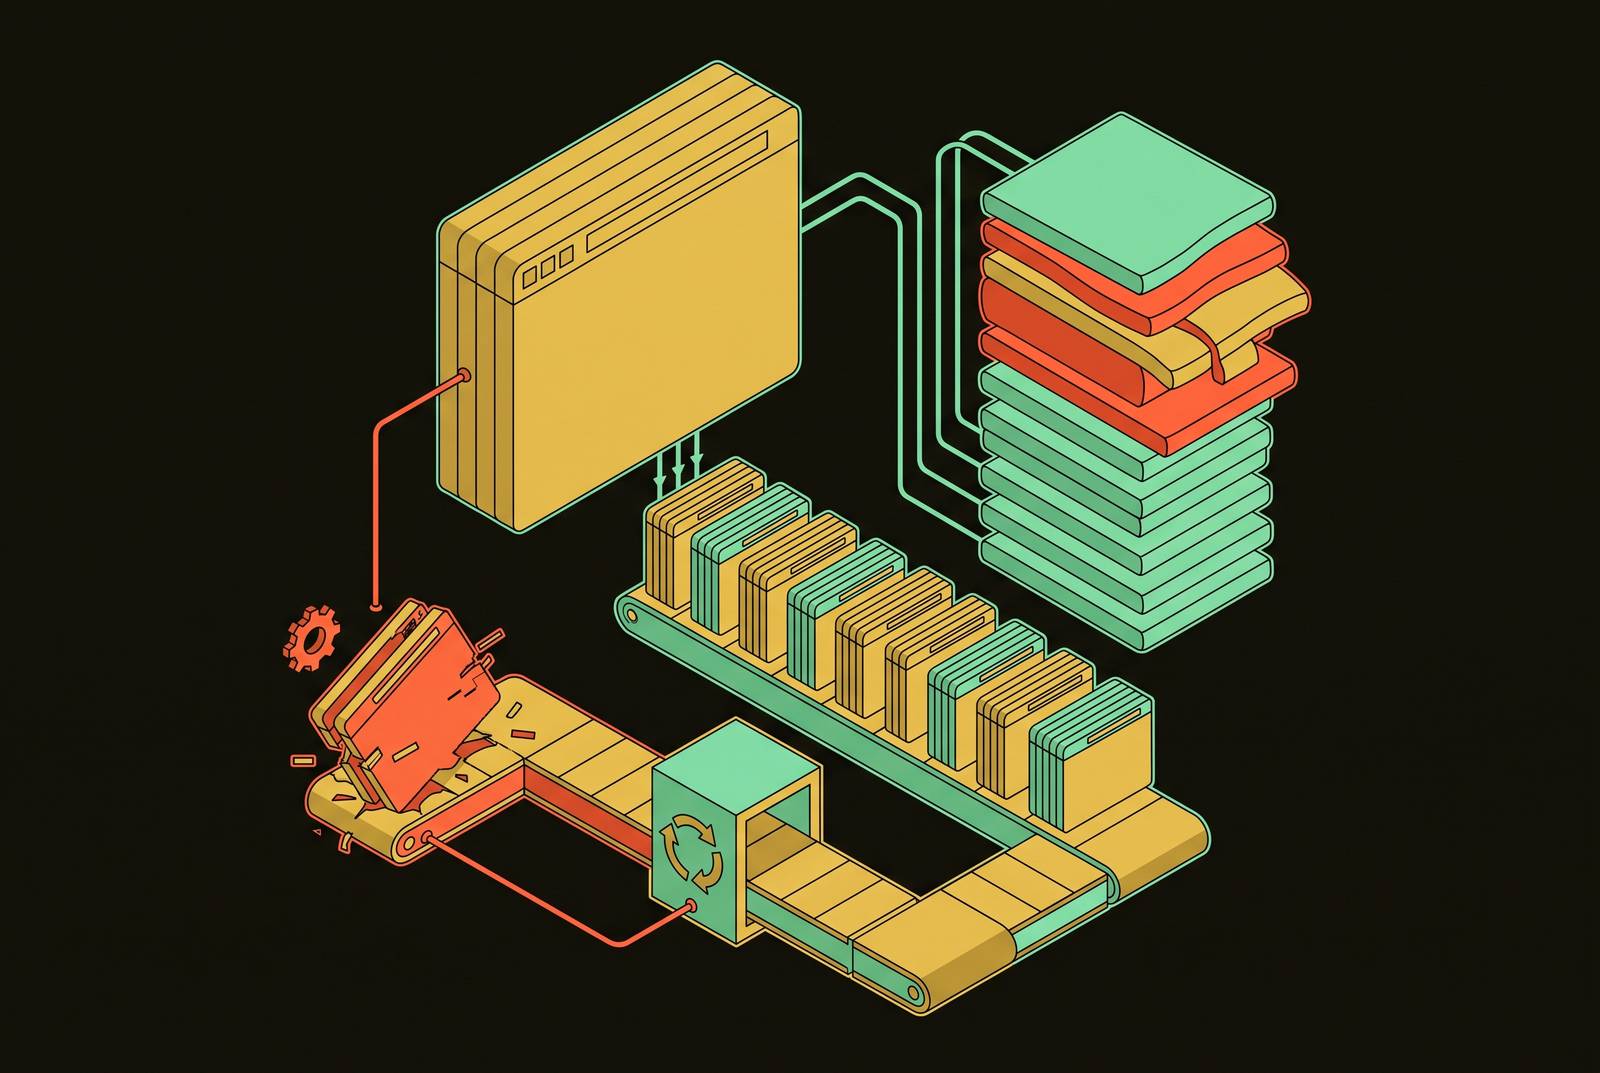
Browser pooling flips the earlier failure modes on their head. Instead of launching a new browser for every request, a fixed set of browser instances runs continuously, and workers check an instance out, use it, and return it when the job finishes. That single change makes memory consumption predictable instead of open-ended.
Launching a browser per request multiplies every problem already described. More launches means more processes, more startup overhead paid repeatedly, and more chances for a context to leak somewhere in an error path. A pool amortizes that startup cost across many page fetches instead of paying it on every single one. Pool size becomes a tunable ceiling on how many browser processes can run at once, and that ceiling translates directly into a ceiling on total memory use.
Inside each pooled browser, contexts (not tabs) are the right unit of isolation. They share the process but keep cookies, cache, and storage separate, so each job gets its own clean session without you paying for a whole new process every time.
Setting pool size isn't a matter of pushing it as high as the server can technically handle. You want the number to sit below the point where memory pressure forces the operating system to start swapping to disk, because a headless Chrome instance that's swapping is worse off than one that simply crashes. A crash is recoverable. A swapping instance just gets slow and unreliable, and it never produces a clear signal that something is wrong.
Pooling alone doesn't finish the job, either. A pool with no restart cycle still accumulates the internal memory growth that happens inside Chrome over time, the same kind of leak described in the section above. The pool controls how wide the system can grow. Something else has to keep the baseline memory use from creeping upward: restart cycles.
Scheduled browser restarts and resource-limit flags as the second layer of containment
A pool caps concurrent memory use on its own, but it can't stop a single browser instance from growing heavier the longer it stays alive. Left unmanaged, a correctly pooled browser will eventually show the same slow memory exhaustion as an unpooled scraper, just delayed. Two additional controls close that gap: scheduled restarts and OS-level resource limits.
The practical fix for internal growth is retiring each browser instance after it has handled a fixed number of pages, then replacing it with a fresh one. There's no universal number that works for every workload. You want to set the restart interval at the point where memory growth becomes measurable but hasn't yet caused real pressure, and finding that point takes monitoring, not a guess written into a config file once and forgotten.
Resource limits set at the operating system level do a different job. Capping memory on renderer processes makes a renderer crash quickly under pressure instead of letting the system swap to disk. That fail-fast behavior keeps the rest of the pool healthy, because a renderer that crashes gives the system something to react to: the pool retires that instance, launches a replacement, and retries the job. A browser that swaps to disk instead just blocks the worker silently, with no error to catch and no obvious cause.
Reducing memory load before it ever becomes a problem helps too. Blocking images, fonts, CSS, and third-party tracking scripts at the network level cuts down per-page memory allocation, since most scraping jobs only need the HTML and the underlying data-fetching API calls, not the full visual rendering a human visitor would see. That reduction works alongside restart cycles rather than replacing them.
Restarts and resource limits aren't settings to configure once and leave alone. You need monitoring infrastructure behind these policies, both to set the right thresholds in the first place and to catch the point where a changing workload makes the old thresholds wrong.
Handling the failure modes headless systems produce that simple scrapers do not: hangs, partial loads, and silent bad results
Even with pooling, restarts, and resource limits in place, headless browsers still fail in ways that never raise an exception. A browser can hang indefinitely. A page can load halfway and stop. A script can stall, and a standard try/catch block will never even notice the error.
An HTTP client that fails gives a clear signal: an error code comes back, and the calling code knows what happened. A headless browser that hangs gives nothing. The worker blocks, the pool slot stays occupied, and whatever system is downstream waiting on that data gets nothing at all, with no indication that anything went wrong.
Partial page loads cause a different kind of damage, and they matter even more when AI pipelines are built on retrieved web content. A page that's only half-rendered can still return text that reads as complete and plausible, even when it's missing the content the scraper actually needed. A language model or a retrieval index has no way to know the content is truncated. It just ingests it as if it were whole.
The fix for hangs is to put explicit timeouts on every individual async step: navigation, waiting for an element, script execution, each with its own limit. A single timeout wrapped around the entire job fires too late to say which specific step actually got stuck. The fix for partial loads is an explicit readiness check: waiting for a specific element to appear, a network-idle state, or a DOM mutation that confirms the actual content the scraper needs has rendered, rather than trusting a generic "page loaded" event that fires regardless of what's actually on the page.
Both of these require the scraper to have a real opinion about what a successful page load looks like for that specific site. This instrumentation has to be written per target rather than applied generically across every job. For AI pipelines specifically, a silent bad result, truncated Markdown, a half-rendered single-page app, a stalled extraction that returns partial content, does more damage than a raised exception would. An exception stops the pipeline and gets noticed. A silent bad result slides into the retrieval index with no signal that anything was wrong, and it stays there until someone notices the model is citing something that was never actually on the page. Silent failures of this kind are a central reason some teams hand the scraping layer to a purpose-built API instead of managing it themselves: the abstraction boundary means resource failures and renderer crashes get caught and handled at the infrastructure level, rather than quietly feeding bad context into a model downstream.
The total operational cost of self-hosted headless infrastructure
Put every mitigation in this piece together, pooling, restart cycles, resource limits, per-step timeouts, process cleanup, and what results is a full managed browser runner, built and maintained indefinitely, sitting alongside whatever the scraping logic itself was supposed to do.
Each mitigation carries its own ongoing cost. The pool needs a scheduler. The restart cycle needs monitoring data to know when to fire. Resource limits need retuning as workloads shift in shape and size. Process cleanup needs container-level tooling that someone has to keep working.
Chrome itself keeps changing, and every one of these mitigations has to be re-audited against each new version. A browser update can shift fingerprint behavior, change memory characteristics, or alter what a given launch flag actually does, and when that happens, you need the same kind of audit any infrastructure dependency requires when it updates.
Running this at real scale, hundreds or thousands of concurrent browser instances, becomes a container orchestration problem in its own right, separate from the scraping logic sitting on top of it. Pod sizing, autoscaling rules, and persistent volume management for /tmp all need decisions, and those decisions need revisiting as traffic patterns change.
This combination of concerns, multi-process overhead on every launch, per-page resource cost that varies by site, and Chrome defaults built for workstations rather than servers, is why many teams choose not to run this infrastructure themselves. A web scraping API built for production pipelines takes on process lifecycle management, resource tuning, and failure recovery as its job, so that the team building on top of it spends its time on extracting and structuring data rather than babysitting browser processes. Context is one option built around that model, handling the infrastructure layer so the scraping logic running on top of it doesn't have to carry pooling, restart policies, and crash recovery as a second full-time job. That tradeoff, control against operational weight, is the real decision between running this in-house or through an API, and it should be weighed against the actual size of the scraping workload before committing to either path.
Sources
- Strategies for minimizing memory usage in headless browsers during web scraping - Headless Browser - Latenode Official Community
- chrome-headless zombie processes
- Add an option to use /tmp instead of /dev/shm [40527382] - Chromium
- Out of memory errors in Headless Chrome 83, seems like --disable-dev-shm-usage is being ignored [40132370] - Chromium