Error Handling and Retry Logic for Web Data API Consumers
Web data APIs fail silently in ways generic error handling can't catch.
Error Handling and Retry Logic for Web Data API Consumers. This article gives developers a practical, category-by-category framework for building resilient integrations against live-web data APIs.
Why web data APIs fail in ways generic REST error handling doesn't anticipate
Most REST error handling runs on one assumption: a failed request either had something wrong with it, so you fix and resend, or it hit a server hiccup, so you wait and retry. Web data APIs (the services that fetch, render, and extract content from live websites) fail in ways that generic REST error handling doesn't anticipate, including transient blocks, partial crawl results, anti-bot responses, and credit exhaustion, which demand a classification-first approach that determines whether to retry, restructure the request, or surface the failure.
The break happens at the HTTP layer itself commercetools API documentation derrick-app.com. A web data API can return a 200, the code that means "everything worked," while the actual payload is a CAPTCHA page, a bot-detection wall dressed up as a normal response, or a JavaScript skeleton with nothing usable inside it commercetools API documentation derrick-app.com. The client sees success. The data is garbage commercetools API documentation derrick-app.com.
That's the headline failure mode, but it's not the only one. A headless browser can time out mid-render and hand back skeleton HTML instead of the page content. Proxy rotation can quietly fail, a residential IP gets banned, a datacenter IP gets blocked at the origin server, and the request goes out looking fine from the client's side. Target sites restructure their pages without warning, and selectors that worked yesterday start returning empty fields or the wrong ones, a problem generally known as schema drift. Credit balances hit zero mid-job and produce a billing-class 4xx that reads, at a glance, like a permissions problem.
A status code chart does not capture any of this. According to APIFreaks' 2026 analysis, a generic log-and-retry approach breaks in production in ways the logs barely explain: concurrency limits get exceeded without anyone noticing, retry loops hammer a server that's already struggling, and credit balances disappear with zero alert commercetools API documentation. Every failure needs to be sorted before anything else happens: does this call for fixing the request, retrying it, or surfacing it as a structured signal to a human? Web data APIs need a richer classification system to answer that, because so many of their failures don't look like failures at all.
A classification system for web data API errors, organized around what action each type demands
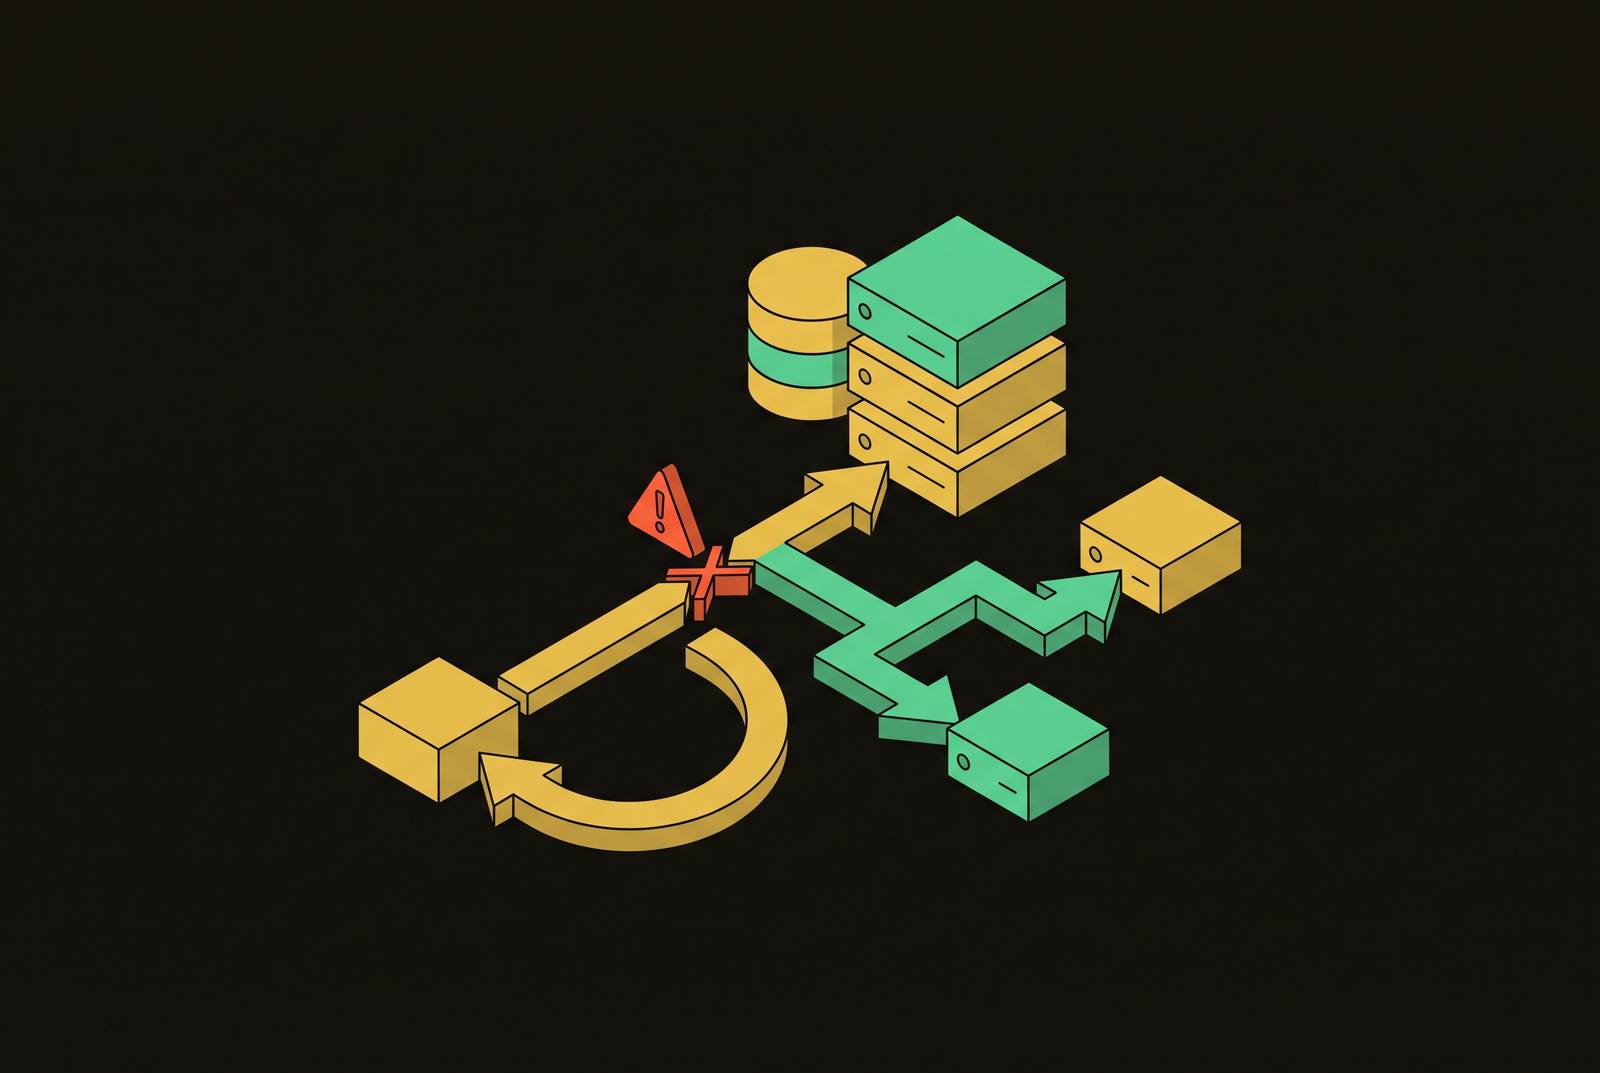
Start with the split that matters most, because getting it backwards is the most common source of bugs that make it to production: fix-first versus retry-first.
Fix-first errors are the 400 range that means something about the request itself is wrong. A 400 for a malformed request, a 401 for missing or invalid credentials, a 402 for payment required, a 403 for permissions, a 406 for an unsupported format. Retry any of these without changing anything and the result is identical every time. It wastes credits and fills the logs with noise nobody reads.
Retry-first errors live in the 5xx range: 500 for an unexpected server condition, 502 for a bad gateway, 503 for overload or maintenance, 504 for a gateway timeout. The request was fine. The conditions on the other end were temporarily wrong, and waiting usually resolves it.
Two codes sit outside that clean split and need their own handling. The first is 429, Too Many Requests. It's a 4xx, which normally signals fix-first, but it's actually retry-first, with a wrinkle.
The second is 404 on lookup APIs, and this one trips up more integrations than it should. A 404 from a WHOIS lookup or a geolocation API, returned because a domain isn't registered or an address is private, counts as a valid answer. Treating it as an exception to catch and retry produces an integration that's technically "working" and practically impossible to debug, because the logs fill up with errors that were never errors.
Then there's the class unique to this domain: the silent failure, which produces an HTTP 200 with the wrong payload underneath it. Soft blocks, a CAPTCHA or bot-detection wall delivered as if it were a normal page. Render failures, skeleton HTML left behind by a headless browser that timed out before the page finished loading. Schema drift, where selectors still technically resolve to something on the page but the something is empty or wrong. None of these trip a status code. All of them require inspecting the body.
Credit exhaustion is a billing-class failure where a balance silently hits zero, producing a 4xx that looks like a permissions error. Session and proxy errors, authentication lost mid-crawl or an entire IP class blocked at the origin, need rotation and a fresh session before any retry makes sense.
Classification is becoming something code can do automatically. The RFC 9457 Problem Details format, covered by Zuplo in 2026, gives a machine-readable type URI alongside status, detail, and extensible fields commercetools API documentation. An integration that parses the type field instead of just the status code gets most of this classification for free, straight out of the response.
Retry mechanics: exponential backoff, jitter, idempotency, and honoring Retry-After
For anything landing in the retry-first bucket, exponential backoff is the baseline. Delay doubles with each attempt, starting from a recommended default around 200 milliseconds commercetools API documentation derrick-app.com. Simple, well understood, and wrong on its own.
Jitter is essential to that, not an addition on top of it. Without jitter, every client hitting the same transient failure at the same moment retries in lockstep, and that synchronized wave slams back into the server at the exact instant it's trying to recover. AWS research cited across the sources shows non-jittered backoff as the worst-performing strategy of the group, by a wide margin. Randomizing the delay spreads the retries out and gives the server room to actually come back.
Retrying forever is its own failure mode. Cap it, somewhere in the range of three to five attempts is the practical ceiling most sources converge on, and then stop derrick-app.com. An integration that never gives up isn't resilient, it's just broken in a way that takes longer to notice. Failing fast past the ceiling and alerting a human beats a silent infinite loop every time derrick-app.com.
Rate limits need one more layer of care. When a 429 comes back with a Retry-After header, honor the exact value. Don't estimate it, and don't shave time off it hoping to sneak in early. That header is doing the guessing for you.
It gets messier than it should be here. The X-RateLimit-* header convention that most engineers treat as an informal standard is, as of 2026, legacy commercetools API documentation. The IETF's draft-11, published in May 2026, defines different field names entirely, and adoption is still early commercetools API documentation. That means client code parsing rate-limit headers has to tolerate divergence across providers rather than hardcoding one naming convention and hoping every API complies commercetools API documentation.
Timeouts deserve the same specificity retries get, and mostly don't receive it. A single global timeout value across every kind of request is a blunt tool for a job that needs precision. Simple resource lookups can run short timeouts with immediate retry on failure. JavaScript-rendered fetches and crawl submissions need meaningfully longer windows, since browser spin-up time alone can eat several seconds before any content shows up. Treating a 60-second default as one-size-fits-all is a mistake apifreaks.com. It's a floor for the slow cases, not a sensible target for the fast ones apifreaks.com.
409 Conflict stands out as its own edge case, especially common in stateful crawl APIs that version their resources. Before retrying an update that hit a 409, check whether the resource state actually changed. Retry against a stale version number and the result is a string of repeated 409s, not eventual success, because the conflict was never about timing in the first place. A failed fetch can always be retried safely, but a failed write needs a check for partial success before it gets retried at all, otherwise idempotency keys become the only thing standing between a retry and a duplicate crawl job burning through credits twice.
Circuit breakers and bulkheads: keeping a failing web data dependency from taking down the rest of a pipeline
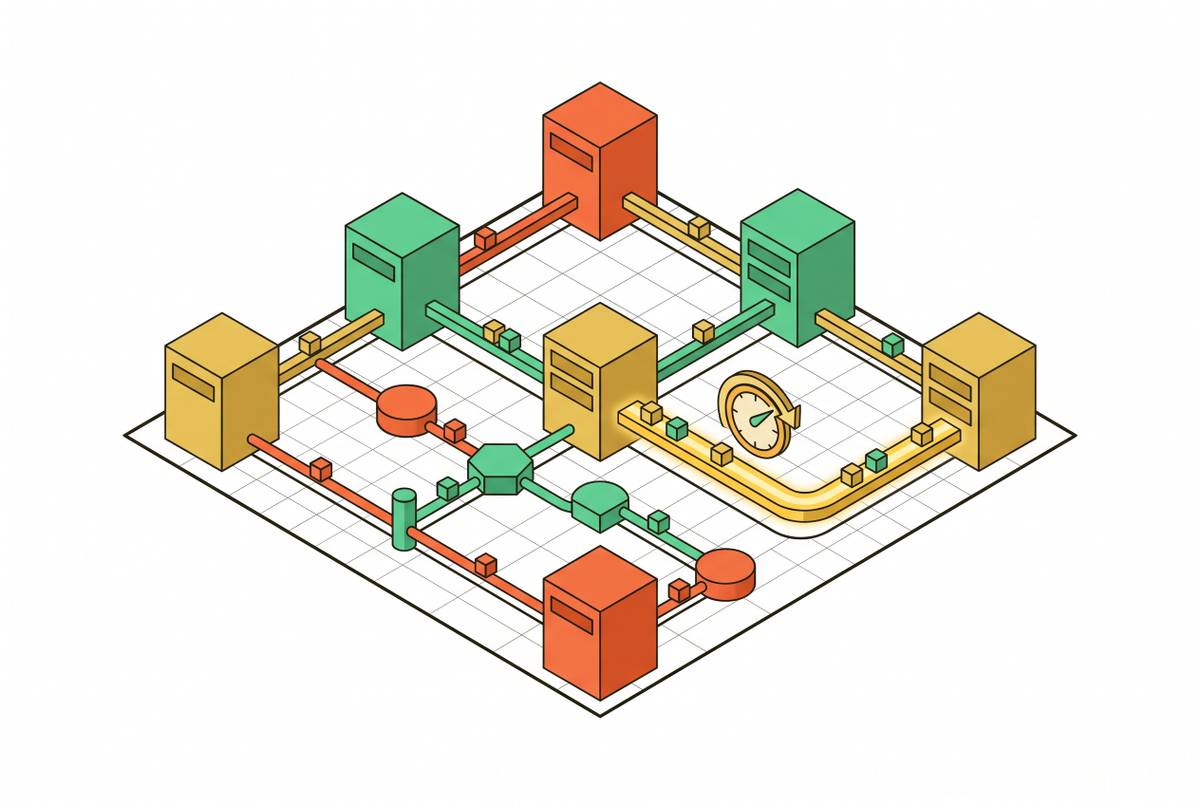
Retry logic handles individual failures. It doesn't handle what happens when a dependency stays down long enough that retries themselves become the problem. A slow web data API triggers retries, retries add pressure, pressure increases latency, latency causes timeouts, and timeouts trigger more retries commercetools API documentation derrick-app.com. That loop is the "unexpected emergent behavior" that appears in incident reviews after the fact, usually described with some version of surprise that a retry strategy caused an outage instead of preventing one.
The circuit breaker pattern exists specifically to break that loop. Wrap calls to the web data API and track the failure rate commercetools API documentation derrick-app.com. Once it crosses a threshold, open the circuit: stop calling the service entirely and return an error immediately instead. After a cooldown period, let one test request through, a "half-open" state, and close the circuit again if it succeeds. The dependency gets space to recover instead of getting hit by a wall of retries the second it shows the first sign of trouble.
Pair that with adaptive throttling, adjusting request rate based on the error rate actually being observed rather than sticking to whatever limit the documentation states. Static rate limits assume the upstream service behaves the way its docs describe. Degraded services don't read their own documentation.
The bulkhead pattern handles a related but separate risk: one failing dependency starving every other part of an application that has nothing to do with it. Isolate web data API calls into their own resource pool, a dedicated thread pool, connection pool, or queue, so that saturation in the scraping layer doesn't choke unrelated API calls sharing the same process. None of this works without explicit timeouts on every outbound call, since a call with no timeout can hold a connection open indefinitely while the other end is failing, turning one slow dependency into a resource leak across the whole application.
This matters more, not less, in AI-native pipelines. Concurrent request patterns common in LLM workflows amplify cascading risk in a way that catches teams off guard, because even a pipeline staying comfortably under documented request thresholds can push into 429 territory just by processing several documents at once. Circuit breakers and per-pipeline concurrency caps need to be part of the architecture from day one. Set the actual open-circuit thresholds from production monitoring, observed p99 latency and real error rates, rather than from documentation estimates that describe how the service behaves when nothing's wrong.
Silent failures: detecting and handling the errors web data APIs don't report as errors
Silent failures don't announce themselves. Detection has to happen in the response body, not the status line.
Soft blocks leave fingerprints if anyone looks. Catch one of those signals and the correct response isn't a generic 5xx retry, it's classifying the call as a proxy or session failure, rotating to a new proxy or session, and retrying from there.
Render failures are visible differently: a JavaScript-rendered page that returns skeleton HTML. The fix is a fallback strategy.
Schema drift is the slowest-burning of the three, and historically the most expensive derrick-app.com. The traditional model has scraper teams building extraction logic once and then maintaining it forever, since every site redesign breaks selectors that used to work fine. According to Kadoa's 2026 research, cited by tendem.ai, that split is roughly 20% of team time spent building scrapers against roughly 80% spent maintaining them, a ratio that says more about the fragility of selector-based extraction than about the teams running it Kadoa, 2026 commercetools API documentation.
Two 4xx codes need special handling outside the standard split. One is self-healing extraction: LLM-based systems that detect a layout change as it happens and remap the extraction logic automatically, adjusting to a site's new structure without a person opening a ticket. The other is schema-driven extraction, where a developer defines the expected JSON schema up front, and any output that doesn't conform to it fails a validation check instead of quietly flowing downstream as malformed data. That second approach doesn't prevent drift, but it makes drift detectable the moment it happens instead of three weeks later when someone notices the numbers look wrong derrick-app.com.
A status-code log does not capture any of this, so the logging strategy has to change to match. Recording payload hash, payload length, extraction field coverage, and schema validation result on every request gives a baseline to compare against, something HTTP status and latency alone will never provide. Indicators of silent failures include the presence of CAPTCHA challenge strings, bot-detection fingerprinting scripts, "access denied" page titles, or unusually short payload length relative to the expected content.
How partial crawl results and long-running jobs change the error handling model
Crawl jobs don't behave like a single request-response pair, and treating them that way is where a lot of this breaks down. Submitting a crawl returns a job ID, not a result, and errors can occur at submission, during queue processing, or during individual page fetches within the run.
Partial results aren't a failure state, they're the normal outcome for any crawl of meaningful size. A crawl across a large site can succeed on the overwhelming majority of URLs and fail on a subset, and the job as a whole is not "failed". The risk isn't the failure itself, it's consuming the output without checking per-URL status, since that silently propagates gaps straight into whatever downstream index or database is waiting for the data.
Handling this well means inspecting status at the per-URL level before results get ingested into a RAG pipeline or a database, and storing the failed URLs for selective retry rather than re-crawling the entire site. It also means telling apart pages that returned actual errors from pages that got skipped due to throttling, since only the throttled ones should go back into an automatic retry queue.
Managed crawl APIs earn their keep here. They handle queuing, per-page retries, throttling, and result pipelines internally. Using one for site-wide ingestion, RAG systems, competitor monitoring, content indexing, offloads an entire error surface that would otherwise need to be built by hand in client code.
Freshness matters too, in a way that doesn't look like an error until it causes one. Setting a freshness TTL per topic in a RAG pipeline decides when a cached crawl counts as stale enough to need a re-fetch. Miss that check and the pipeline serves outdated embeddings without ever throwing an error, a pure data-quality failure with no visible signal attached to it. And for jobs that run for hours, credit exhaustion partway through terminates the run silently unless it's being watched. Credit balance checks belong in pre-job validation, not just as something inspected after a job has already failed.
Observability requirements for web data pipelines: logging and alerting
Status code distribution, latency percentiles, error rate: standard stuff, and necessary. None of it catches the silent failure classes that make up so much of what actually goes wrong in this domain.
Closing that gap means logging more than the usual fields. Payload length and payload hash per request, since both give a baseline for spotting soft blocks and render failures the moment they deviate from normal. Extraction field coverage, tracking what percentage of the expected schema actually got populated. Schema validation results per extraction, with field-level detail on what passed and what didn't. Retry attempt count and final outcome per job, which separates a transient blip that resolved itself from a persistent failure dressed up as one. Credit balance before and after any high-volume job, so a silent drain doesn't go unnoticed until the job stops running entirely.
Alerting needs the same precision as classification did earlier, because treating everything as equally urgent is its own failure mode. Alert on a soft block rate climbing above baseline, a rising schema validation failure rate, a credit balance dropping below a set floor, or a circuit breaker opening. Treat as expected variance: 404s on lookup APIs, since those are valid data states rather than errors, individual page failures inside an otherwise successful partial crawl, and single-request timeouts that still fall within the retry budget.
Correlation ties all of it together. Every outbound request should carry a unique request ID, and every mutation should carry an idempotency key, so a retried request, a partial result, and whatever error occurs downstream can all be traced back to the same originating call. That's the whole point of building the classification system in the first place: not fewer errors, but errors that explain themselves the moment they occur.